Training-free Verifiable Process Reward for LLM Reinforcement Finetuning
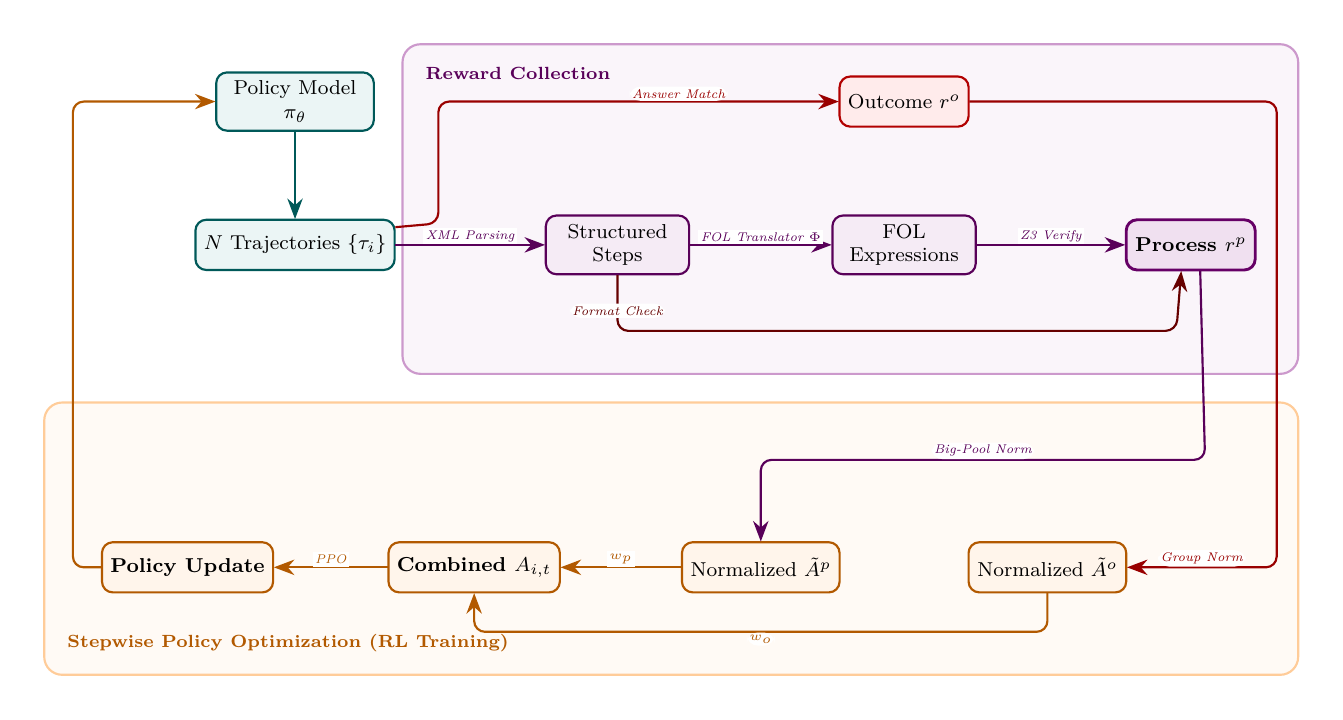
This thesis project, started in October 2025, develops a training-free verifiable process reward for reinforcement finetuning of large language models. The implementation is available in the verl repository.
Approach
- Forcing LLMs generate natural-language reasoning steps in Horn clause form, such as \(p \land q \to r\), so the reasoning process can be segmented into semantically meaningful steps.
- A theorem prover or solver acts as a verifier and checks each reasoning step.
- A teacher LLM formalizes natural-language reasoning into verifier-compatible expressions.
- A GRPO-like advantage normalization method estimates critic-free values for process rewards.
Evaluation
Experiments use logical and mathematical question-answering datasets. The system is evaluated by comparing reasoning-model accuracy before and after reinforcement finetuning with the proposed process reward.